Manuscripts under review · u.2
Speaking Without Sound: From Face and Head Motion to Silent Speech Command Input on Face-Tracked Headsets
under review
Video figure
Abstract
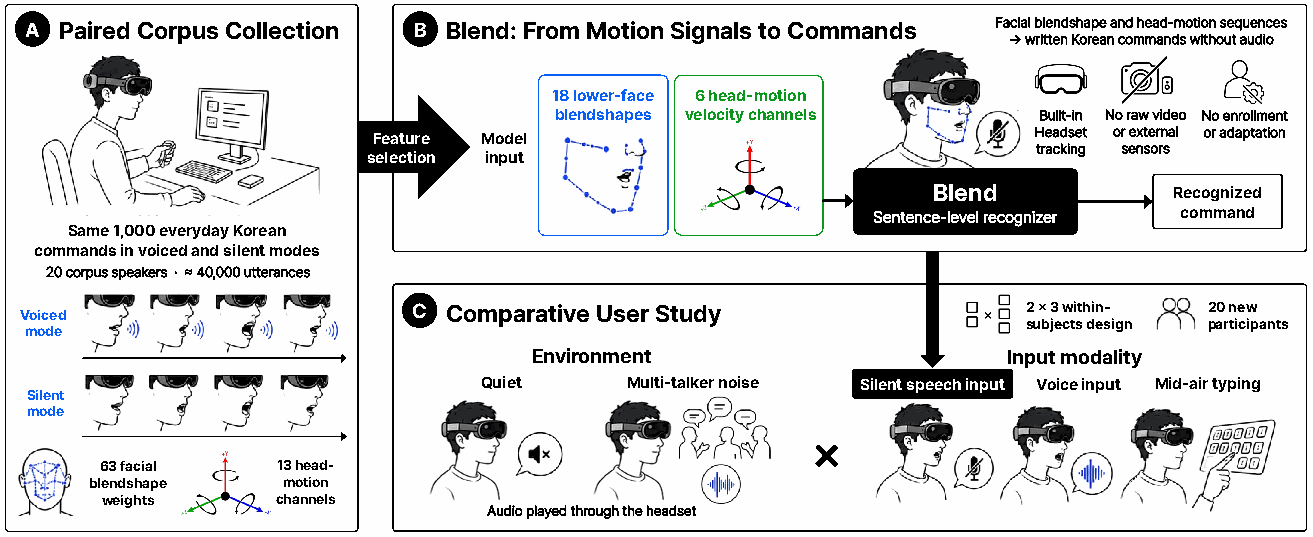
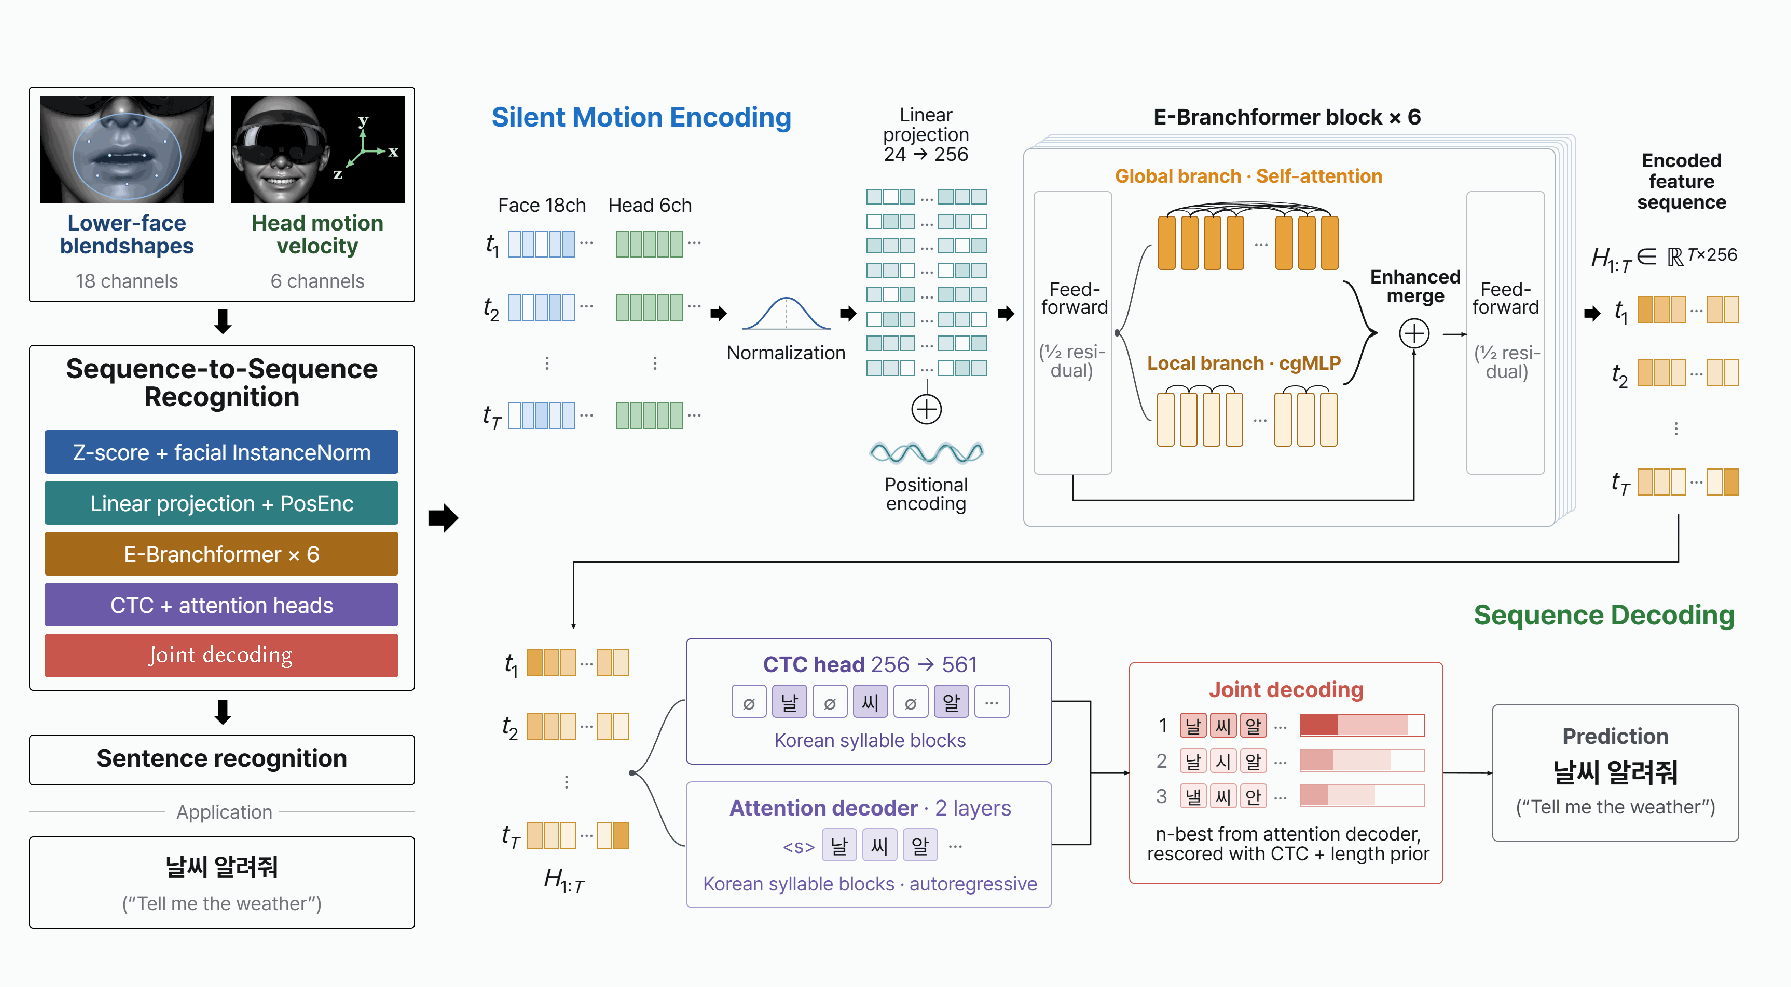
Noise, privacy concerns, and social settings can make voice input impractical. To explore silent speech, we collected 40,000 voiced and silent utterances of 1,000 Korean commands from 20 speakers using a face-tracked headset. Silent articulation involved larger mouth-related blendshape amplitudes, less head motion, and substantial variation across speakers, but no reliable duration difference. Using blendshape weights and head motion, we developed Blend for sentence-level recognition, achieving a mean character error rate of 12.00% for held-out speakers within this command set without enrollment or adaptation. In live evaluation, 20 new participants compared silent speech, voice, and mid-air typing in quiet and multi-talker noise. Silent speech involved longer entry times than voice, yet usability and most workload dimensions did not differ significantly. It also elicited lower social-privacy concerns and higher overall willingness-to-use ratings. Typing supported correction but was slower and more demanding. These findings support silent speech as a complement to voice.